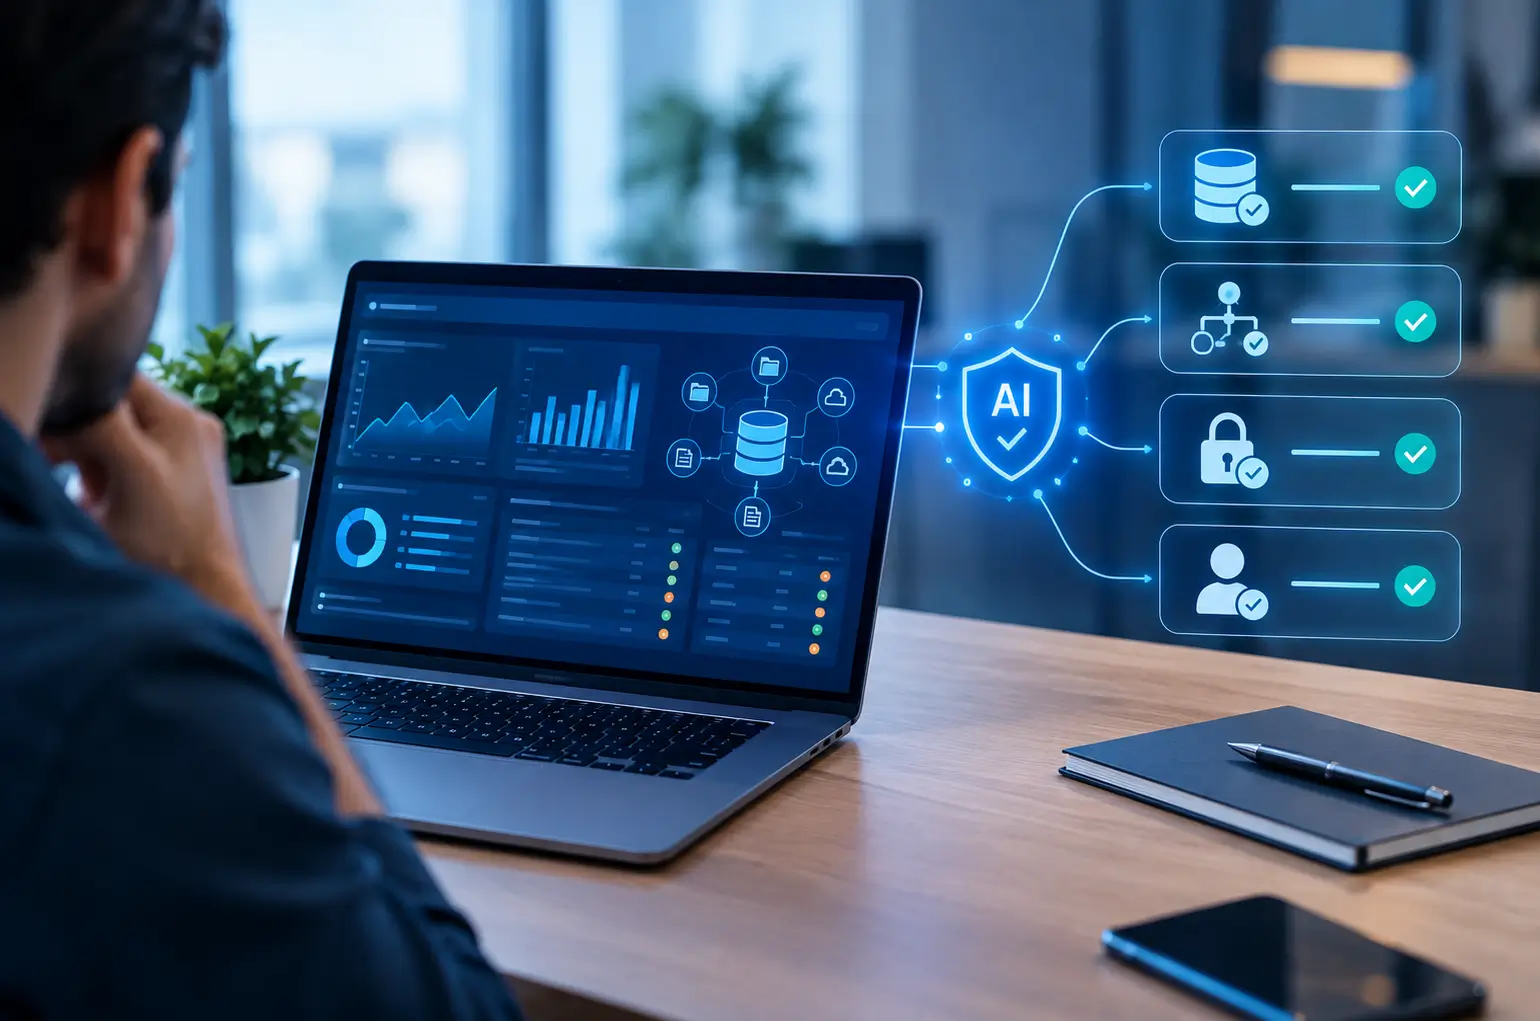
An AI readiness assessment checks four things before a build is scoped. Whether the data exists at the volume and history the model needs. Where each field came from and who last changed it. Who can read it, and under what control. And who is accountable when the output is wrong.
The demo you approved ran on records that someone selected. Your production data was selected by nobody. That gap is where most healthcare and fintech AI purchases quietly fail, and it surfaces after the contract is signed.
I audit data, systems, and ownership for payers, provider networks, and health technology firms before a single requirement is written. This article gives you the checks I run, the evidence that settles each one, and the questions to put in front of a vendor during a procurement review.
Key Takeaways
- An AI readiness assessment covers four domains. Data availability, lineage, access control, and ownership. A vendor demo evidences none of them.
- The 2026 State of Data Integrity and AI Readiness survey of 505 data and analytics leaders found 87% believe their data is AI-ready, while 43% name data readiness as the most significant barrier to AI alignment.
- Only 31% of those leaders hold metrics tied to KPIs, so most buyers cannot prove whether an AI program is working after go-live.
- Ask for evidence, not answers. Every item in the AI readiness checklist below is paired with the artifact that settles it.
- A data gap found before signature is a requirement. The same gap found after signature is a change request you pay for.
What an AI Readiness Assessment Checks Before Anyone Writes Code
An AI readiness assessment is narrow on purpose. It covers one use case against one dataset, not your wider technology plan.
Four domains, each with a pass or fail answer:
- Data availability: Do the volume, history, and label quality exist for this use case? A claims denial model needs years of adjudicated outcomes, not one clean quarter.
- Lineage: Can you trace a single field from source system to model input, including every transformation and the job that applied it?
- Access control: Who can read the training set, who approved that access, and does the log hold up under review?
- Ownership: When a field definition changes, who signs it off, and who answers for a wrong model output?
The fourth domain sinks more projects than the first three combined. Data quality is fixable on a timeline. An unowned data domain is a standing argument between two departments, and no vendor resolves that for you. Availability and lineage failures usually trace back to the same place: the data pipeline that feeds the model, which is why the audit starts at the source systems rather than at the model.
Audit the Data Before You Scope the Build
We evidence data availability, lineage, access control, and ownership against your own systems, then publish the scoring method so your risk team can challenge the rating rather than accept it.
Why a Vendor Demo Proves Nothing About Data Readiness for AI
The 2026 State of Data Integrity and AI Readiness survey of 505 data and analytics leaders found that 87% believe their data is AI-ready. In the same survey, 43% named data readiness as the most significant barrier to AI alignment. Those are not two groups. They are the same people answering two questions, and the distance between the answers is the risk you underwrite at signature.
The pattern repeats in almost every engagement I see. A referral classification model performs well on a demo corpus of digitized letters from one specialty. Production holds a decade of scanned correspondence across nine specialties, two of which changed systems mid-decade. The model was never the problem. The intake was, and nobody asked for record counts by specialty and by year before approving the build.
Data readiness for AI is measured on your records, in your environment, with your access rules applied. Anything demonstrated on a curated extract tells you the vendor can build. It tells you nothing about whether you can supply. The AI and data work we deliver for healthcare organizations starts at the same place every time, with the source systems and the people who own them.
The AI Readiness Checklist to Run Before You Sign
This AI readiness checklist tests data readiness for AI inside a procurement review. The value sits in the second half of each line. Answers are easy to give. Evidence is not.
- Which source systems hold the fields this model needs?
Evidence: a field level inventory naming system, table, and owner. - How many records exist per class, per year, for the last five years?
Evidence: query output your own team can rerun. - What share of required fields is null, free text, or inconsistently coded?
Evidence: a dated profiling report run against production, not a sample. - Can you trace one record end to end?
Evidence: a lineage trace for a single identifier, from source row to model input. - Who holds read access to the training set today?
Evidence: an export of the current access list with approver names and dates. - Where does regulated data enter the pipeline, and where is it masked?
Evidence: a data flow diagram with the masking step marked and the test that proves it runs. - Who signs off a field definition change?
Evidence: a named owner per data domain, in writing, with a change log. - What baseline will you measure the model against?
Evidence: today’s denial rate, handling time, or false positive rate, measured before the model exists.
Item eight is where the 31% figure bites. If you cannot state today’s number, you will not prove improvement twelve months from now. Measure it before the vendor arrives.
What an AI Readiness Assessment Tool Can and Cannot Score
An AI readiness assessment tool earns its place on the countable work. Automated profiling returns null rates, cardinality, duplicate counts, and schema drift across large tables faster than any analyst. Most catalog platforms map system-to-system flows well enough to start a lineage trace.
No tool scores the rest. Whether a label means what the clinical or risk team assumes it means. Whether the owner named in the catalog still works there. Whether an access approval was granted deliberately or inherited during a migration three years ago. Those answers come from interviews, and a scoring engine cannot conduct one. Treat any AI readiness assessment tool as an input to the audit rather than the audit itself.
How an AI Maturity Assessment Differs From a Pre-Build Audit
An AI maturity assessment scores the organization. Skills, governance, funding, tooling, and operating model, usually across five levels. It is useful for planning multi-year investment and close to useless for a purchase decision due in three weeks.
The two get confused in procurement, so here is the split:
- Unit measured: An AI maturity assessment scores the enterprise. An AI readiness assessment scores the specific data this model will consume.
- Output: Maturity work returns a level and a set of improvement themes. The audit returns a pass, a conditional pass with named remediation, or a stop.
- Timing: Maturity work runs annually. The audit runs between shortlist and signature.
Both have value. Only one answers the question a procurement lead has to answer this month. The NIST AI Risk Management Framework is a reasonable reference on the governance side, and it treats data documentation and provenance as measurable functions rather than policy statements.
Working With Regulated Health and Financial Data
ViitorCloud engineered a healthcare platform that has processed $192.2M in revenue and pipelines ingesting more than 1 million data points a day. Bring us the source systems, not the slide deck.
What Enterprise AI Readiness Looks Like in Healthcare and Fintech
Regulated data raises the bar in two domains. Access control and lineage stop being engineering hygiene and become evidence you produce for someone else.
The HIPAA Security Rule requires audit controls over systems holding electronic protected health information. During an AI build, that log is what proves who touched the training set and under what approval. If you cannot produce it for the last twelve months, enterprise AI readiness is not a scoring exercise. It is a remediation project, and it belongs inside the contract rather than after it. In fintech, the artifact changes and the principle does not. Enterprise AI readiness and data readiness for AI rest on the same two files: an access list with approvers and a lineage trace that survives questioning.
Scale makes the same point. On the healthcare revenue platform we engineered for LogixHealth, $192.2M in revenue has been processed through the system. On Cow Monitor, the pipeline ingests more than 1 million data points a day from 15,000+ sensors, and the deployment cut livestock mortality by 30%. In both cases, the modeling was the shorter half of the work. Deciding which fields were trustworthy, who owned them, and how they would be refreshed took longer and decided the outcome. The same holds when moving an AI pilot into production, because ingestion assumptions that held on pilot volumes rarely survive live ones.
Take the Checklist Into Your Next Procurement Review
Eight questions, each paired with the artifact that answers it, sized for a single vendor review cycle. We will run it alongside your IT, risk, and procurement leads before you shortlist.
Where I Would Start Your AI Readiness Audit
An AI readiness audit does not need a quarter. For one use case, the four domains can be evidenced in two to three weeks, most of it spent pulling artifacts that already exist and interviewing the three or four people who know what the fields actually mean.
ViitorCloud has been building AI and data systems since 2011 for more than 300 clients, including regulated environments across healthcare, finance, and government. We publish the scoring method we use, so your risk and procurement teams can challenge a rating instead of accepting it. If a domain fails, you get the remediation named and sized before scoping. Reviewing how an AI readiness assessment is structured is a sensible first step, and if you want the audit run against your own systems, talk to our AI engineering team before you shortlist.
The Question to Answer Before You Sign
Vendor evidence and buyer evidence are two different files. The demo proves the vendor can build. Only an AI readiness assessment run against your own systems proves you can supply the data that the build depends on.
Three things to do this week. Pull the record counts by class and by year. Export the access list for the training data and check who approved each entry. Name an owner for every data domain the model will touch. If any of the three takes more than a day, you have found the gap the demo hid.
The 87% who believe their data is ready and the 43% who name data readiness as their biggest barrier are the same people. Run the audit, and you find out which group you are in before the contract is signed rather than after.
Vishal Shukla
Vishal Shukla is Vice President of Technology at ViitorCloud Technologies.
Frequently Asked Questions
What does an AI readiness assessment actually check?
It checks four domains against one use case. Data availability, meaning volume, history, and label quality. Lineage, meaning traceability from source system to model input. Access control, meaning who can read the data and who approved it. Ownership, meaning who signs off definition changes and who answers for wrong output.
How long does an AI readiness audit take?
Is an AI readiness assessment the same as an AI maturity assessment?
Can an AI readiness assessment tool replace a manual audit?
What should we ask a vendor before signing an AI contract?