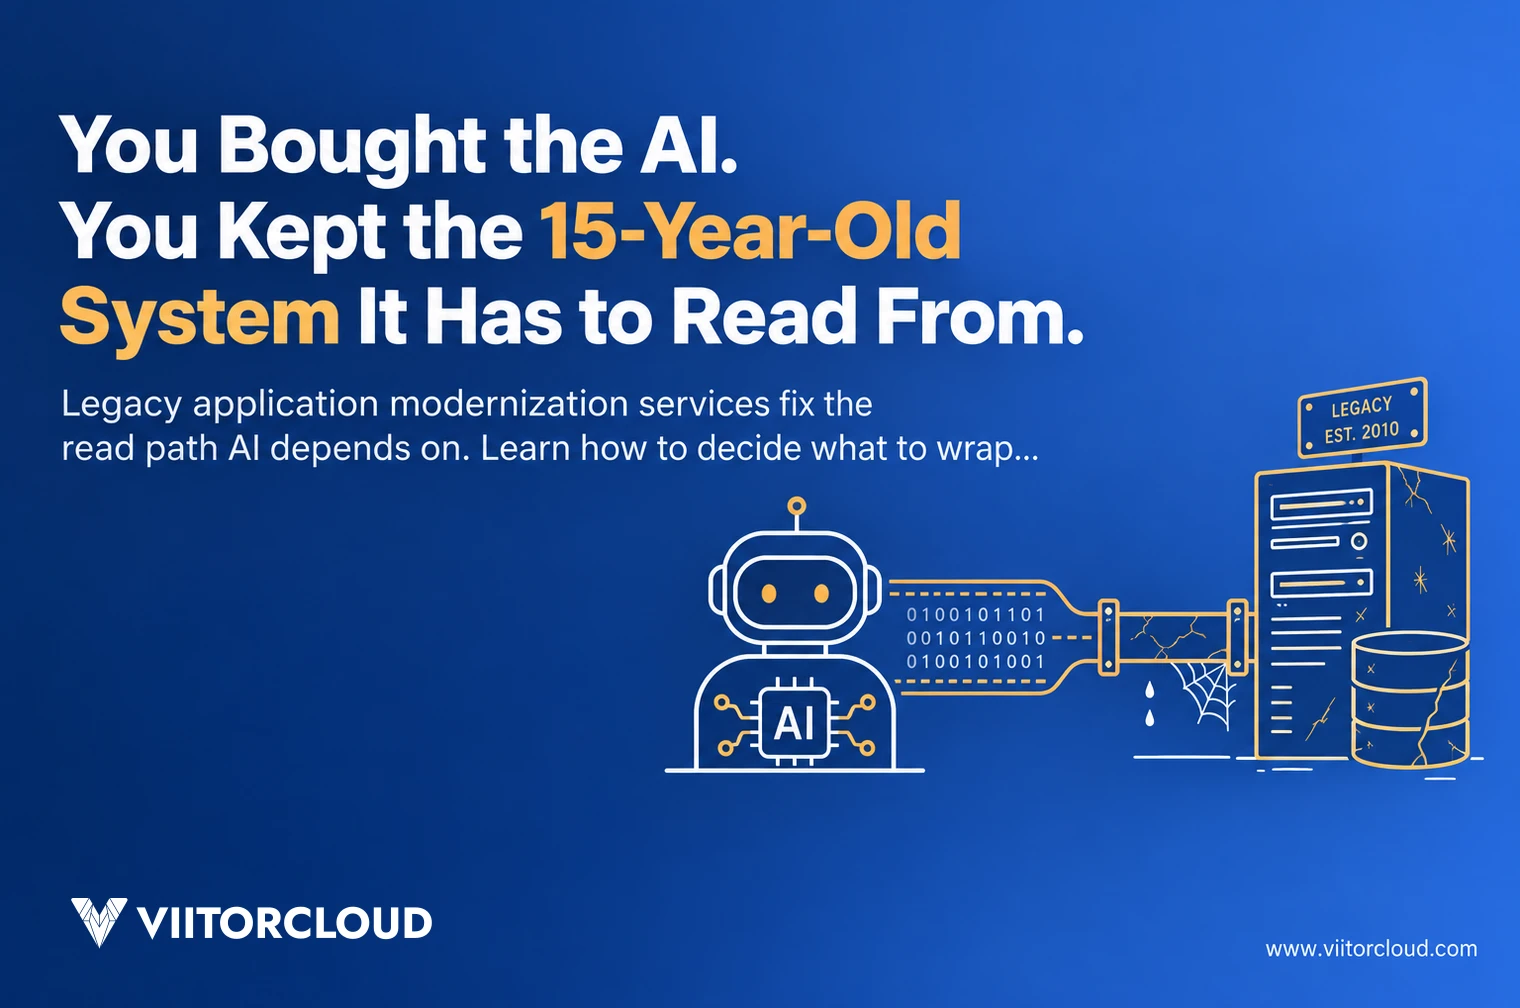
AI fails on legacy systems for three measurable reasons. The data the model needs sits in tables no outside service is allowed to query; the core answers in minutes or hours when the model needs milliseconds, and the record it returns is incomplete because half the context lives in a second system. Legacy application modernization services fix that read path first.
You bought the AI. You kept the 15-year-old system it has to read from.
I get called into stalled AI programs often enough that the first meeting has a script. Someone reports the model is underperforming. Someone else suggests a better model, more training data, or a different vendor. Then I ask how the model gets its data, and the room goes quiet.
What follows is the part most AI budgets skip. Which parts of your core to wrap behind an API, which to migrate, and which to retire, and why that sequence has to be settled before anyone picks a model.
Key Takeaways
- AI on an old core fails at the read path, not at the model. Access, latency, and completeness are the three things to test before you evaluate a single vendor.
- The wrap, migrate, or retire decision belongs inside legacy application modernization services, not inside the AI plan. Each path has a specific test, and getting it wrong costs a rebuild.
- Wrapping is the fastest route to legacy data access for AI and the most dangerous one, because an API publishes a broken data model faster.
- Cloud application modernization services earn their budget on latency by moving AI reads off the transaction path your core cannot afford to slow down.
- ViitorCloud has run this sequence on production systems that cannot go down, including a port platform live across 14 sites in more than 10 countries.
Why AI Fails on a Fifteen-Year-Old Core System
A model is only as good as the system it reads from. That is obvious, written down. It stops being obvious when the AI budget is approved in one meeting, and the core platform underneath it is never mentioned.
Research published by RAND found that more than 80% of AI projects fail, roughly twice the rate of technology projects that do not involve AI, with inadequate data among the leading causes. That matches what I see in lending and payments. The data exists. The system holding it cannot serve it in the shape or the timeframe the model needs.
Three failure modes account for most of it:
- Access: The core exposes a fixed report set and nothing beyond it. Anything else requires a change request against a codebase two contractors still understand.
- Latency: A platform designed for overnight batch runs answers in hours. A fraud check, a credit decision, or a routing call needs an answer in under a second.
- Completeness: The customer record is split across the core, a bolted-on CRM, and a spreadsheet operations maintains by hand. The model sees a third of the customer and scores confidently on it.
One lending platform I reviewed scored applications against a nightly extract. By the time the model ran, its view of the applicant was up to fourteen hours old. Nobody had misrepresented the model. It was accurate on stale inputs, which is a different thing. This is what legacy application modernization services exist to fix, and it is why they belong inside the AI budget rather than beside it.
Map Your Core Before You Pick a Model
Every engagement starts with a six-week map of what each system holds, how fast it answers, and which components to wrap, migrate, or retire.
What Legacy Data Access for AI Actually Requires
Legacy data access for AI is not a reporting problem with a new label. Reporting tolerates a day-old answer. A model sitting in a live decision path does not.
Four things have to be true before a model can read from a system built before any of this was a requirement.
- A query path that does not touch the transaction core.
If the model competes with production traffic for the same database, someone will eventually switch the model off to protect the core.
- Sub-second reads on the fields the decision uses.
Not the whole schema. Identify the twenty or thirty fields that drive the outcome and serve those fast.
- One complete view of the entity.
Customer, account, claim, or shipment, assembled from every system that holds part of it, with each field definition agreed and written down.
- Change capture instead of extracts.
The core should announce what changed rather than being asked every night, which is where real AI-powered data pipeline development earns its cost.
Getting legacy data access for AI right is most of what legacy application modernization services actually deliver. It is also the only part that survives every future model change, which is why I fund it first.
How to Decide Whether to Wrap, Migrate, or Retire
Every component of an old core belongs in one of three buckets. Legacy system modernization services exist to make that call component by component, not system by system. The mistake is treating it as a technology preference rather than a test. Here is the test I apply to each path.
Wrap It Behind an API
- The test: The data model is still correct, and the business logic is still right. Only the access method is wrong.
- What you get: The fastest route to legacy data access for AI, usually weeks rather than quarters, with no change to the code running the business.
- What it costs: Nothing structural gets fixed. If the data model underneath is wrong, the API publishes the wrong answer faster.
Migrate It
- The test: The business logic is worth keeping, but the platform cannot meet the latency, scale, or compliance requirements; however, it is wrapped.
- What you get: A component that can be read at speed, scaled on its own, and changed without a release freeze across the entire core.
- What it costs: Time and dual running. Budget for both systems being live at once and for the reconciliation that proves they agree.
Retire It
- The test: The function is duplicated elsewhere, unused, or serving a process the business walked away from years ago.
- What you get: Less surface area to modernize and one fewer source of the conflicting records that make model output look wrong.
- What it costs: Political capital. Someone always defends a report nobody has opened since 2019.
The U. S. Government Accountability Office has documented critical systems still running decades past their intended life, several written in languages with a shrinking pool of engineers able to maintain them. Commercial cores are rarely that old, but the pattern holds. Components survive because nobody was ever asked to decide whether they should. If the question is whole-system rather than component level, refactoring or replacing a legacy application is a separate decision, and I have covered that comparison elsewhere.
Built for Systems That Cannot Go Down
ViitorCloud modernizes live cores, including a port platform active across 14 sites in more than 10 countries and a healthcare platform that has processed $192.2M in revenue.
Where Cloud Application Modernization Services Change the Latency Math
The reason to bring in cloud application modernization services is not the hosting bill. It is that the cloud gives you somewhere to put the read path that is not the core.
Three moves do most of the work:
- A dedicated serving layer: AI reads hit a replica or a purpose-built store, never the transaction database.
- Event streaming off the core: Changes publish as they happen, so the serving layer stays current without nightly jobs.
- Independent scaling: Model traffic can spike without the core being sized and paid for at that peak.
Cloud application modernization services also change what compliance work looks like. Encryption, key management, access logging, and data residency get handled at the platform layer instead of being retrofitted into an application that predates the rules. For a lender or a payments business, that is often the argument that releases the budget, and it is where most of our BFSI technology work begins.
Why Legacy Application Modernization Services Come Before Model Selection
Sequencing is the whole argument. Legacy application modernization services are not a prerequisite you get to skip because the AI is the interesting part of the roadmap.
Order the work this way:
- Map which system holds each field the decision needs, and how fast each one can return it.
- Apply the wrap, migrate, or retire test to every component, and write the reasoning down.
- Build the serving layer and the change capture.
- Then choose the model.
Teams that invert steps three and four spend the first quarter of an AI project writing integration code inside the model application, where it is invisible to the rest of engineering and impossible to reuse.
A freight operator I worked with wanted accurate arrival predictions. The prediction logic was straightforward. The hard part was that vessel, yard, and customs status lived in three systems with three different definitions of a completed move. More effort went into agreeing what counted as an arrival than into the model. That is normal, and it is why legacy system modernization services get scoped before the data science does.
What Application Modernization Consulting Services Should Deliver First
Good application modernization consulting services produce four artifacts before any code is written.
- A field-level map from the decision the AI has to make back to the systems that hold the inputs.
- A latency budget for each read, measured against the current core rather than estimated.
- A wrap, migrate, or retire verdict per component, with the test that produced it.
- A sequence with dependencies, so the work can be funded in stages instead of as one large commitment.
If a proposal for application modernization consulting services opens with a target architecture and no measurement of the current one, it is a diagram, not a plan. Our system integration and modernization engagements start with the measurement.
Unblock the AI You Already Bought
If your model returns stale or incomplete answers, the fix is in the read path. Talk to an engineer who has sequenced this work on a fifteen-year-old core.
How I Sequence This Work on a Live Core Platform
I am confident about the order because ViitorCloud has run it on systems that cannot go down. The ZARA port management platform we built for DP World is live across 14 active sites in more than 10 countries, tracking container and general cargo movements since 2016. The healthcare revenue platform we engineered for LogixHealth has processed $192.2M in revenue. The government records platform delivered with KPMG in Tamil Nadu carries more than 70 million registered citizens.
None of those began as AI projects. Every one required the same decision about an existing estate before anything intelligent could sit on top. Legacy system modernization services on a live core are mostly about sequencing, not rewriting. If your AI work keeps stalling on a core that cannot serve data fast enough or completely enough, our legacy application modernization services start with that six-week map rather than a rebuild proposal.
What to Fix Before the Next AI Budget Cycle
Three things to take from this. The model is rarely the reason AI answers come back stale or incomplete; the read path is. The wrap, migrate, or retire decision has a specific test for each path and belongs in the modernization plan rather than the AI plan. And legacy application modernization services scoped before model selection cost far less than the same work discovered halfway through an AI build.
Start with the map. One page per system, listing what it holds, how fast it answers, and which of the three paths it belongs on. If that map does not exist, the AI project is running on assumptions about data nobody has checked. Book the assessment before the next model evaluation, not after it.
Vishal Shukla
Vishal Shukla is Vice President of Technology at ViitorCloud Technologies.
Frequently Asked Questions
Why does AI fail on legacy systems?
AI fails on legacy systems because of access, latency, and completeness. The model cannot query the data it needs, the core answers far slower than the decision requires, and the record it returns is missing context held in other systems. The model is accurate on bad inputs, which looks like model failure.
Should I wrap, migrate, or retire my legacy core?
How long does legacy data access for AI take to fix?
What do application modernization consulting services actually deliver?
Do I need cloud application modernization services to run AI on legacy data?